Index-Translate: Meaning and Instructions, Together
For character dialogue, voice matters. For reader-facing explanations, tone and formatting matter. For internet memes, meaning often goes beyond the literal words. The same sentence can call for more than one good translation.
Index-Translate combines multilingual translation, instruction following, and meme understanding. Alongside the source text and target language, you can specify how the translation should read: preserve forms of address, use a more conversational tone, or return only the translation. The model uses these requirements to produce text suited to its intended use.
Teasing, irony, and cultural references require an understanding of why something is said that way. We include social and cultural context in our evaluations and assess translation instruction following separately, checking both the quality of the translation and whether the requested constraints were met.
Index-Translate is built upon Qwen 3.5 2B/9B/35A3B base and trained through three stages:
Mid-train: At this stage, we adopt a standard WSD scheduler, mixing pre-training replay corpora, multilingual corpora, parallel corpora, and pivot corpora. We explored diverse data ratios, parallel alignment, and parallel organization methods, specifically increasing the proportion of pivot corpora during the annealing phase, enabling the model to learn cross-lingual semantic correspondences and expressions across diverse languages, laying a solid foundation for downstream translation tasks.
Post-train: Building on the multilingual foundation from mid-train, we trained three separate expert models—a general translation model, an instruction-following translation model, and a meme translation model—conducting SFT and RaR RL (Rubric as Reward) or RLVR for each.
Model-merge: Combining linear interpolation, MOPD, and Mix-RL, we consolidated multi-version capabilities into a unified model.
Post-Training Benchmark: Six Core Metrics
The main table summarizes post-training results for Index-Translate-9B/2B and comparison models across FLORES-200, WMT24++, instTrans, IFMTBench, the domain mean, and MEME translation. Index-Translate-9B ranks first overall on both instTrans (0.8949) and MEME (0.7331); 2B also substantially leads its comparisons.
| Model | FLORES-200 COMET-22 ↑ |
WMT24++ COMET-22 ↑ |
instTrans IFscore ↑ |
IFMTBench IFscore ↑ |
Domain mean COMET-22 ↑ |
Meme MEME ↑ |
|---|---|---|---|---|---|---|
| Index-Translate checkpoints | ||||||
| Index-Translate-9B | 0.8781 | 0.8597 | 0.8949 | 0.8524 | 0.8325 | 0.7331 |
| Index-Translate-2B | 0.8649 | 0.8485 | 0.8359 | 0.7241 | 0.8261 | 0.6429 |
| Comparison models | ||||||
| Hy-MT2-1.8B | 0.8522 | 0.8401 | 0.5613 | 0.6887 | 0.8165 | 0.3643 |
| Hy-MT2-7B | 0.8747 | 0.8593 | 0.6928 | 0.8483 | 0.8205 | 0.5139 |
| Hy-MT2-30B-A3B | 0.8787 | 0.8624 | 0.7177 | 0.8726 | 0.8338 | 0.5812 |
| translategemma-12b-it | 0.8732 | 0.8524 | 0.3664 | 0.2675 | 0.8237 | 0.4281 |
| CohereLabs/North-Small-Translate-1.0 (218A25B) | 0.8784 | 0.8578 | 0.6035 | 0.8383 | 0.8243 | 0.6836 |
| gpt-5.6-sol | 0.8650 | 0.8469 | 0.8231 | 0.9026 | 0.8171 | 0.7194 |
| gemini-3.5-flash-lite | 0.8750 | 0.8497 | 0.7810 | 0.8684 | 0.8066 | 0.7034 |
Domain mean is the unweighted average across six domain datasets. MEME evaluates cultural nuance and internet memes. Bold indicates best score in each column. ↑ Higher is better.
Full Index-Translate evaluation: seven categories and interactive radar chart ↘
Capabilities in Real Translations
From low-resource languages to explicit instructions and internet memes, these three examples show the source text, translation requirements, and actual saved model outputs. Recorded source text, prompts, and model outputs are kept in their original languages.
A Chinese Story, Retold in Polish
This Chinese-to-Polish fiction example shows how the model translates a narrative while following an explicit instruction about whom a pronoun refers to.
Translate into Polish. The source phrase “等她” refers in context to the male character Zou Yan. Return only the translation.
邹衍站在原地说不出的委屈,他本以为两女在门口等她,怎么也会决个胜负,留下一个陪他。
让他也炫耀虚荣一般,难道我就这么命苦吗?
对不起了,昨天电源踢掉了,稿子都没了,尽力补。Zou Yan stał w miejscu, czując niewypowiedzianą krzywdę. Myślał, że obie kobiety będą na niego czekać przy drzwiach i że w końcu rozstrzygną między sobą, która zostanie z nim.
Chciałby chociaż trochę pochwalić się swoją dumą. Czy naprawdę mam tak pechowe życie?
Przepraszam, wczoraj padło zasilanie i straciłem cały manuskrypt. Postaram się to nadrobić.What to look for: “na niego” and “z nim” convey “waiting for him” and “with him.” The input explicitly supplied this pronoun clarification.
Full input and example record
请将以下中文小说翻译成波兰语,并且严格遵循所有约束要求。

【源文】
邹衍站在原地说不出的委屈,他本以为两女在门口等她,怎么也会决个胜负,留下一个陪他。
让他也炫耀虚荣一般,难道我就这么命苦吗?
对不起了,昨天电源踢掉了,稿子都没了,尽力补。

【约束要求】
1. 【注意】指代一致性——源文第一句'他本以为两女在门口等她'中的'她'容易误指为两女中的一位,实际应为'他'(指邹衍自己),可能为笔误。翻译成波兰语时需注意代词性别一致,避免歧义。


只输出译文,不要有任何额外说明。
Example ID: trans-004 · Model: qwen35_9b_linear_3model_0.8_0.1_0.1. Source and output are preserved from the repository records without rewriting.
Translate the Content. Preserve the Tags and Terms.
This input combines three requirements: preserve HTML tags, use specified terms, and write in an everyday conversational style. Compare the source and output to check each requirement.
Translate into Korean and preserve HTML tags. Use 배터리 컨디션 for battery health, 휴대용 밥통 for power bank, and 생명줄 for charging cable. Use everyday speech and return only the translation.
<div class="chat-msg">天呐,这<span class="bad">充电宝</span>太坑了!<br>拿<i>数据线</i>连上半天,电量不增反降,真让人抓狂。<b>电池健康</b>迟早被搞废,还能不能好好玩了?</div><div class="chat-msg">세상에, 이 <span class="bad">휴대용 밥통</span> 진짜 최악이잖아!<br><i>생명줄</i>로 반나절이나 연결했는데, 배터리가 차는 건 고사하고 오히려 줄어들다니, 진짜 미치겠네. <b>배터리 컨디션</b>도 조만간 다 망가질 텐데, 이걸로 제대로 놀 수 있긴 한 거야?</div>What to look for: the div, span, br, i, and b tags are retained, and all three specified terms appear in the corresponding places. Tags are shown as text so their structure can be inspected directly.
Full input and example record
请将以下这段中文HTML代码片段翻译成韩文。在翻译过程中,请务必严格保持所有的HTML标签原样不变。此外,请遵循指定的术语映射要求:将“电池健康”译作“배터리 컨디션”,将“充电宝”译作“휴대용 밥통”,并将“数据线”译作“생명줄”。最后,请确保整体译文呈现出日常口语化的表述风格。

<div class="chat-msg">天呐,这<span class="bad">充电宝</span>太坑了!<br>拿<i>数据线</i>连上半天,电量不增反降,真让人抓狂。<b>电池健康</b>迟早被搞废,还能不能好好玩了?</div>

注意仅输出翻译内容,不要其他任何解释
Example ID: ifmt-002 · Model: qwen35_9b_linear_3model_0.8_0.1_0.1. Source and output are preserved from the repository records without rewriting.
Free Games and a Dusty Library: How Does the Joke Travel?
This gaming-community post combines slang about adding another free game to a library, claiming freebies, leaving games unplayed, and Epic Games. The original input explains the references and asks the translation to preserve a casual community tone.
Translate into German and preserve HTML. “白嫖” means claiming a game for free, “入库吃灰” means claiming it without playing it, and “e宝” refers to Epic Games. Keep the gaming-community tone.
The reading view appears below. The full HTML is retained in the example details.
xdm关于e父的喜加一

我想吟下此诗:

静观其变,白嫖就好,入库吃灰,能要就要

敬请期待,e宝开造。Leute, was das nächste Gratis-Spiel von Epic angeht:
Ich muss da mal dieses Gedicht rezitieren:
Warte einfach ab, hol’s dir umsonst, lass es im Bibliotheksregal stauben – wenn’s geht, nimm’s!
Bleibt dran, Epic legt los!What to look for: the output uses “hol’s dir umsonst” for claiming a freebie, “lass es im Bibliotheksregal stauben” for leaving it to gather dust in the library, and “Epic” for the affectionate nickname for Epic Games.
Full input and example record
请将以下中文专栏文章翻译成德语,并且严格遵循所有约束要求。

【源文】
<p>xdm关于e父的喜加一</p><p><br></p><p>我想吟下此诗:</p><p><br></p><p>静观其变,白嫖就好,入库吃灰,能要就要</p><p><br></p><p>敬请期待,e宝开造。</p><p><br></p><p></p><p></p>

【约束要求】
1. 【硬性要求】保留源文中的 HTML 格式标记不变
2. 【注意】消除歧义——文中'白嫖'为网络游戏用语,指不花钱免费获取游戏/资源,而非字面意义上的'嫖娼';'入库吃灰'指领取后放入库中却不游玩;'e宝'指Epic Games平台(昵称)。这些均需保留原网络黑话风格并意译。
3. 【注意】译文保持口语化网络聊天/游戏社区用语风格,不随意切换语体或语气

只输出译文,不要有任何额外说明。
Original source HTML
<p>xdm关于e父的喜加一</p><p><br></p><p>我想吟下此诗:</p><p><br></p><p>静观其变,白嫖就好,入库吃灰,能要就要</p><p><br></p><p>敬请期待,e宝开造。</p><p><br></p><p></p><p></p>
Original model output, including HTML
<p>Leute, was das nächste Gratis-Spiel von Epic angeht:</p><p><br></p><p>Ich muss da mal dieses Gedicht rezitieren:</p><p><br></p><p>Warte einfach ab, hol’s dir umsonst, lass es im Bibliotheksregal stauben – wenn’s geht, nimm’s!</p><p><br></p><p>Bleibt dran, Epic legt los!</p><p><br></p><p></p><p></p>
Example ID: trans-001 · Model: qwen35_9b_linear_3model_0.8_0.1_0.1. Source and output are preserved from the repository records without rewriting.
These historical examples come from an existing 9B model and show outputs for the given inputs. They do not establish overall performance across all languages or model variants.
 Text and instructions → Translation
- Add your text. Choose the source and target languages, then enter the text to translate.
- Set your requirements. Specify tone, forms of address, or output format. Custom instructions use the 9B version.
- Read the translation. The translation appears progressively as it is generated, making it easy to read and inspect.
Index-Echo: Let Another Language Be Heard
Narration, dialogue, and commentary in video need to reach audiences through sound. Index-Echo takes source speech as input and generates the translation as target-language speech, letting the content be heard in a new language.
Index-Echo is an end-to-end S2S (Speech-to-Speech) translation model supporting speech translation and dubbing in 6 languages. With fast inference for dialogue and video clips, it makes the path from hearing the original to receiving translated speech more efficient.
S2TT: speech in, translated text out. An AuT encoder is connected to Index-Translate-2/9B, and the speech translation task is trained end-to-end.
S2ST: speech in, translated speech out. Building on S2TT, the CosyVoice3 tokenizer is removed, and the LLM's last hidden representations are connected to CosyVoice3's semantic layer. Training proceeds in two stages: first, the LLM and CosyVoice3 are frozen while an approximately 30M-parameter mapper is distilled to align the representations; then the participating model parameters are unfrozen and trained end-to-end with DiffRO. Speaker voice information is extracted from the source audio and used for speech generation; it currently supports translation and dubbing from Chinese/English into 6 target languages.

Evaluation Highlights
In S2TT evaluation, Index-Echo-9B achieves an MT judge score of 0.857, ranking first in this comparison. Index-Echo-2B achieves a TS st_MAE of 0.395, the lowest timestamp deviation in this comparison (9B is second at 0.488).
The current online workflow starts with a Bilibili video and provides translated subtitles, proper-name and terminology settings, and a separate dubbing entry point. You can review the text before proceeding to dubbing.
 Video → Subtitles and dubbing
- Provide a video. Paste a Bilibili video URL, BV ID, or av ID, and select the target language.
- Review translated subtitles. Specify proper names and terms as needed, and export bilingual ASS subtitles.
- Continue to dubbing. Use the separate dubbing action to continue producing the video's voiceover.
Index-Homura: Translation That Fits the Rhythm of Dubbing
A line spoken in a few seconds can become much longer in another language. Cross-language dubbing therefore needs to do two things at once: preserve the meaning and fit the script into the original time window.
Index-Homura is a translation model with syllable control, designed for dubbing. You can set a target syllable-ratio range so that length becomes part of the translation task. The ratio is the number of translated syllables divided by the number of source syllables; the current online demo specifies length using a target syllable count.
Making length control a training objective. The HOMURA method uses GRPO reinforcement learning to combine a dynamic syllable-ratio reward with a translation-quality reward, jointly optimizing length constraints, meaning preservation, and fluency. The reward interval accounts for differences between target languages and the coarse granularity of counting syllables in short sentences, teaching the model to choose wording that fits the budget.
Evaluation Highlights
In the Sandglass evaluation, Index-Homura-9B achieves a composite score of 0.8660, ranking first on this leaderboard. The share of outputs with syllable deviation no greater than 10% is 81.92%, with a control slope of 0.968 (ideal: 1).
One Source, Different Syllable Budgets
From scenic narration to character dialogue, these three Chinese-to-English examples show actual outputs under different target syllable counts.
Scenic Narration: One Night View, Two Expressions
Chinese source这座城市的夜景,比我想象中还要美。
This city's night view is even better than I thought.
The city's night view is even more beautiful than I imagined.
From “better than I thought” to “more beautiful than I imagined,” the description of the same scene changes with the budget.
Urgent Dialogue: Preserve the Action and the Deadline
Chinese source快走,天黑之前我们必须离开这里。
Go, we have to leave before it's dark.
Go quickly, we have to leave before it gets dark.
Both versions preserve the need to leave before dark. The larger budget adds “quickly” to convey urgency.
Video Opening: An Invitation to Explore
Chinese source欢迎来到我们的频道,今天我们一起探索海底世界。
Welcome to our channel, today we're exploring the world beneath the sea.
Welcome to our channel, today we're going to explore the underwater world together as a team.
With a larger budget, “the world beneath the sea” becomes “the underwater world,” and the invitation to explore together is expressed more fully.
These are unedited outputs from the current online demo. Target syllable counts are input constraints, not a guarantee that every output hits the target exactly. Syllable counts also do not map directly to dubbing duration; length-control performance requires dedicated evaluation.
Example provenance and version notes
Generated through the Homura online demo on September 22, 2026. Twelve outputs were recorded, and three pairs are shown without editing. The frontend currently calls the model alias index-mt-2b-syllable; these examples do not establish the performance of the released Index-Homura 9B weights.
This small set illustrates behavior and is not used to estimate constraint hit rates or overall quality. Full input and output records ↗
 Dialogue and syllable count → Dubbing script
- Enter Chinese dialogue. Choose English, Arabic, Spanish, or Japanese as the target language.
- Set the target syllable count. Use the slider or numeric input to specify the desired translation length.
- Review the script. Check its meaning and length before preparing the voiceover.
Index-NaiLong: A Whole Novel, in One Pass
Long documents expose a clear weakness in specialized translation models. In this Chinese-to-English evaluation, Hy-MT2-7B falls on GuoFeng from 0.7334 at 4K to 0.0001 at 64K, and on BWB from 0.7167 to 0.0001. By 16K, the two scores have already fallen to 0.0197 and 0.0334. Specialized translation ability does not automatically extend to reliable long-document translation.
Even frontier models can face a serious bottleneck in long-form output. LongWriter (2024) observed that the frontier models evaluated at the time could accept long contexts yet struggled to generate sufficiently long text on request. Translating a whole novel requires sustained source coverage, consistent characters and plot, and a translation that reaches the end. A larger context window alone does not demonstrate these abilities.
Index-NaiLong targets long inputs and outputs and supports generating the complete translation of a novel in one pass. We make full-length translation a core task, examining output completeness, consistency of character names and forms of address, and continuity across passages, with the goal of producing a complete work that can be used further.
Evaluation Highlights
At 64K tokens, Index-NaiLong 9B scores 0.7983 and 0.7239 on GuoFeng and BWB Chinese-to-English translation, respectively, and 0.7816 on cross-domain books translated from English to Chinese. The full results report performance across all length tiers.
In the online demo, you can upload a document, read the translation as it is generated, and download the result. The current demo processes documents in segments and presents Chinese-to-English translations progressively.
 Long document → Downloadable translation
- Upload a document. Provide Chinese content in TXT or Markdown format.
- Read the translation in segments. The demo processes the document in chunks and displays English results as they become available.
- Download the translation. Save the result as Markdown or PDF for further use.
Evaluation
Detailed evaluations for Index-Translate, Index-Echo, Index-Homura, and Index-NaiLong follow. Each model uses test sets and metrics appropriate to its task.
Index-Translate: Text Translation
We organize text translation evaluations into seven categories: instruction following, books, subtitles, social and cultural context, FLORES, WMT, and low-resource languages.
Among the models in the current comparison, the 9B text model ranks first in instruction following and subtitle translation, and in the top two in five categories. The 2B model ranks third in instruction following. These scores apply only to the evaluated text-model checkpoints, not to 35B-A3B, Homura, NaiLong, or Echo. Their mapping to the final Index-Translate release weights remains to be verified.
| Category | Index-Translate-2B | Index-Translate-9B | 9B rank / Models evaluated |
|---|---|---|---|
| Translation instructions | 0.78170 | 0.87550 | 1 / 13 |
| Book translation | 0.80915 | 0.81620 | 2 / 13 |
| Subtitle translation | 0.83225 | 0.83655 | 1 / 13 |
| Social and cultural translation | 0.72795 | 0.77900 | 2 / 13 |
| FLORES | 0.86490 | 0.87810 | 3 / 13 |
| WMT | 0.84850 | 0.85970 | 2 / 13 |
| Low-resource translation | 0.73310 | 0.79800 | 4 / 13 |
Values are unweighted means of the raw metrics within each category; higher is better. All seven categories include 13 models.
On individual benchmarks, Index-Translate-9B achieves an instTrans_minor IFscore of 0.8792, while Index-Translate-2B scores 0.7851, ranking first and second among the reported results. On the subtitle benchmark MuST-Cinema , the 9B model scores 0.8979 COMET-22; on MEME , it scores 0.7331, ranking second among the reported results.
| Model | Raw mean | Relative score |
|---|
Scales are fixed using per-category normalization across all available models; changing the selection does not rescale the chart. Missing values remain gaps. “Best non-Index” uses the best baseline in each category and is not a single model.
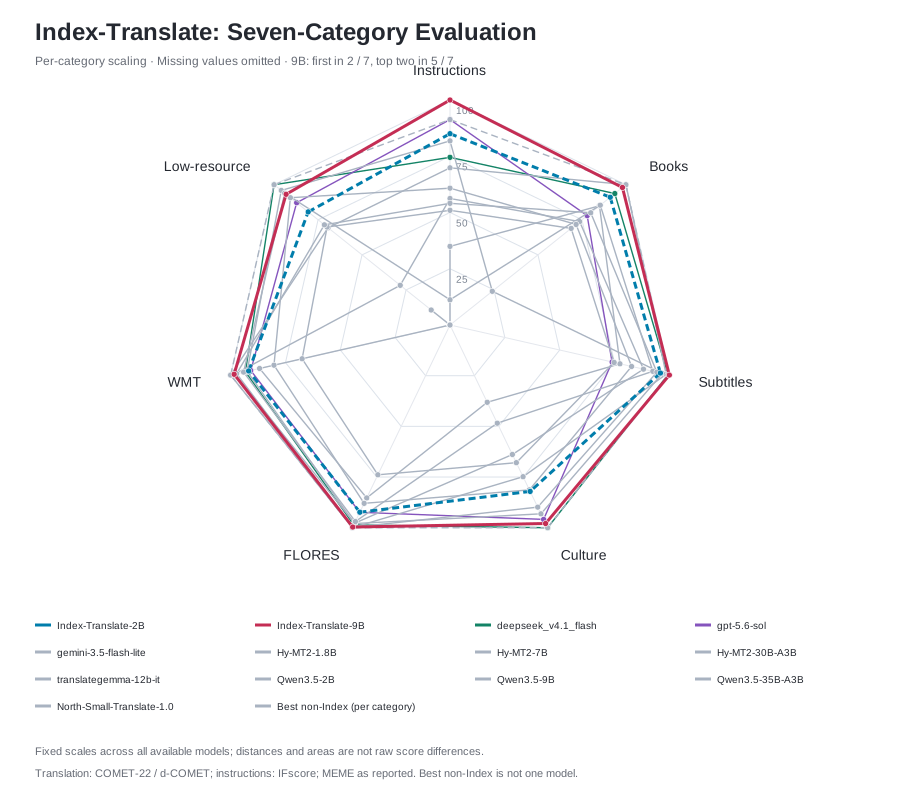
Each category is independently normalized to 0–100 to show relative positions. Distances and areas do not represent raw score differences or overall capability.
Rankings reflect numerical order in the current data, without significance testing. For example, the top two subtitle-category means differ by 0.00065; this does not establish a statistically significant lead.
Download 12 raw benchmark scores · Download all seven-category means
Index-Echo: Speech Translation
Index-Echo evaluations cover both S2TT (Speech-to-Text) and S2ST (End-to-End Speech-to-Speech) tasks. S2TT evaluates translation semantics and subtitle timestamp alignment, while S2ST evaluates target-language content accuracy (WER/CER), translation quality (MT judge), and speaker voice preservation (cosine similarity).
S2TT Evaluation Results: Speech Input, Text Output
S2TT evaluation is based on an in-house video subtitle test set. Index-Echo-2B achieves the lowest TS st_MAE (0.395), with 9B second (0.488). For MT judge, Index-Echo-9B scores 0.857, ranking first among evaluated models; Index-Echo-2B scores 0.825, significantly outperforming open-source firered_audio (0.448).
| Model | MT judge ↑ | TS st_MAE ↓ |
|---|---|---|
| Index-Echo-9B | 0.857 | 0.488 |
| gemini-3.1-pro-think | 0.849 | 1.824 |
| Index-Echo-2B | 0.825 | 0.395 |
| firered_audio | 0.448 | 0.765 |
Benchmark dataset: in-house video subtitle test set. ↓ Lower is better; ↑ higher is better. Bold indicates the best value in the column.
S2ST Evaluation Results: End-to-End Speech Translation & Dubbing
S2ST evaluation is based on an in-house video subtitle test set across English (EN), Spanish (ES), and Japanese (JA). Japanese uses CER, while English and Spanish use WER; speaker voice preservation is measured by source-speaker cosine similarity. Index-Echo-2B leads significantly on Japanese CER (0.027 vs. pipeline 0.123 and SeamlessM4T-v2 0.468), and also achieves the best English WER (0.039) and Japanese speaker similarity (0.785).
| Model / Pipeline | Translation Quality (EN / ES / JA) MT judge ↑ |
English (EN) | Spanish (ES) | Japanese (JA) | |||
|---|---|---|---|---|---|---|---|
| Content WER ↓ |
Speaker Cosine ↑ |
Content WER ↓ |
Speaker Cosine ↑ |
Content CER ↓ |
Speaker Cosine ↑ |
||
| Index-Echo-2B End-to-end S2ST |
0.905 / 0.823 / 0.838 | 0.039 | 0.715 | 0.090 | 0.744 | 0.027 | 0.785 |
| Native Pipeline s2tt+cosyvoice3 pipeline |
0.905 / 0.823 / 0.838 | 0.042 | 0.724 | 0.131 | 0.748 | 0.123 | 0.779 |
| SeamlessM4T-v2 No voice cloning capability |
0.370 / 0.343 / 0.310 | 0.066 | 0.077 | 0.058 | 0.099 | 0.468 | 0.140 |
Benchmark dataset: in-house video subtitle test set. MT judge evaluates translation quality. Content measures speech error rate (EN/ES use WER ↓, Japanese uses CER ↓). Speaker measures cosine similarity to source voice ↑ (SeamlessM4T-v2 does not perform voice cloning). Bold indicates best score.
Index-Homura: Syllable Control
In the Sandglass syllable-control evaluation, Index-Homura-9B ranks first among the 20 models and training variants on this leaderboard, with a composite score of 0.8660. Across 3,600 examples, 81.92% of outputs have a syllable deviation of no more than 10%. The control slope is 0.968, close to the ideal of 1, indicating that output length responds to the target syllable budget.
The evaluation covers 300 real subtitle lines, four target languages—English, Japanese, Arabic, and Spanish—and three length targets: short, natural, and long. The table compares Index-Homura-9B with all eight external baseline configurations.
| Model | Composite score ↑ | Syllable reward ↑ | Translation quality ↑ | Deviation ≤10% ↑ | Control slope ≈1 |
|---|---|---|---|---|---|
| Index-Homura-9B | 0.8660 | 0.9457 | 0.7863 | 81.92% | 0.968 |
| Hy-MT2-7B | 0.6700 | 0.4839 | 0.8560 | 18.86% | 0.195 |
| Hy-MT2-30B-A3B | 0.6566 | 0.5577 | 0.7554 | 22.39% | 0.340 |
| Qwen3.5-9B | 0.5946 | 0.4708 | 0.7183 | 16.39% | 0.430 |
| Qwen3.5-35B-A3B | 0.5937 | 0.4011 | 0.7863 | 13.25% | 0.249 |
| Hunyuan-MT-7B | 0.5455 | 0.3722 | 0.7188 | 15.11% | 0.031 |
↑ Higher is better; the control slope should be as close to 1 as possible. Bold indicates the best value in each column. Each model is evaluated on 3,600 examples.
The composite score measures both length control and translation quality. Hy-MT2-7B scores 0.8560 on translation quality, above Index-Homura-9B at 0.7863. Index-Homura-9B achieves a syllable reward of 0.9457 and an 81.92% rate of deviation within 10%, reflecting the benefit of training for dubbing-length constraints.
Index-Homura-9B Results by Language
| Target language | Examples | Composite score ↑ | Translation quality ↑ | Deviation ≤10% ↑ |
|---|---|---|---|---|
| English | 900 | 0.8675 | 0.7950 | 78.67% |
| Japanese | 900 | 0.8941 | 0.8300 | 86.67% |
| Arabic | 900 | 0.8527 | 0.7661 | 79.89% |
| Spanish | 900 | 0.8496 | 0.7539 | 82.44% |
Index-NaiLong: Long-Document Translation
This evaluation covers GuoFeng, BWB, and cross-domain books, in both Chinese-to-English and English-to-Chinese directions, with five length buckets from 4K to 64K tokens. Index-NaiLong 9B stays above 0.79 across all GuoFeng buckets and scores 0.7816 on cross-domain books at 64K.
GuoFeng · ZH→EN
| Model | 4K | 8K | 16K | 32K | 64K |
|---|---|---|---|---|---|
| Hy-MT2-7B | 0.7334 | 0.2872 | 0.0197 | 0.0006 | 0.0001 |
| Qwen3.5-9B | 0.7688 | 0.7300 | 0.7458 | 0.7200 | 0.5788 |
| Qwen3.8 Flash | 0.7974 | 0.7956 | 0.7572 | 0.6826 | 0.4710 |
| Index-NaiLong 9B | 0.8014 | 0.8042 | 0.8075 | 0.8057 | 0.7983 |
BWB · ZH→EN
| Model | 4K | 8K | 16K | 32K | 64K |
|---|---|---|---|---|---|
| Hy-MT2-7B | 0.7167 | 0.2387 | 0.0334 | 0.0024 | 0.0001 |
| Qwen3.5-9B | 0.7545 | 0.7487 | 0.7201 | 0.6419 | 0.5643 |
| Qwen3.8 Flash | 0.7683 | 0.7676 | 0.7387 | 0.6262 | 0.5085 |
| Index-NaiLong 9B | 0.7745 | 0.7680 | 0.7681 | 0.7600 | 0.7239 |
Cross-domain Books · EN→ZH
| Model | 4K | 8K | 16K | 32K | 64K |
|---|---|---|---|---|---|
| Hy-MT2-7B | 0.8246 | 0.3157 | 0.0335 | 0.0004 | 0.0057 |
| Qwen3.5-9B | 0.8749 | 0.8785 | 0.7724 | 0.5891 | 0.5179 |
| Qwen3.8 Flash | 0.8945 | 0.8910 | 0.8837 | 0.8582 | 0.5299 |
| Index-NaiLong 9B | 0.9002 | 0.8799 | 0.8960 | 0.8745 | 0.7816 |
Get started
The Index-translate family includes four models. Choose your content type and desired output to open the corresponding demo.
| Model | Variants | Core capabilities | Try it |
|---|---|---|---|
| Index-Translate | 2B / 9B / 35B-A3B | Text translation across 100+ languages, instruction following, and meme understanding | Text translation ↗ |
| Index-Echo | 2B / 9B | End-to-end S2S, fast inference, and speech translation across 6 languages | Video speech translation ↗ |
| Index-Homura | 9B | Control translation length using a target syllable-ratio range | Syllable-controlled translation ↗ |
| Index-NaiLong | 9B | Long-form generation and complete translated novels in a single pass | Long-document translation ↗ |